A team reconstructs a purchase forecast for 1 September. The extract already contains a payment from 10 September, and the model uses it as a feature. It finds buyers almost perfectly in historical data. On the actual launch date, however, that future payment is unknown, so the production system cannot reproduce the result.
The dates, amounts and results below are illustrative. For a marketing director, forecast assessment has two parts: evaluating selection using information available in time, and establishing the value of the action that follows. A model may identify likely buyers well while a discount merely reduces money from purchases that would have happened anyway.
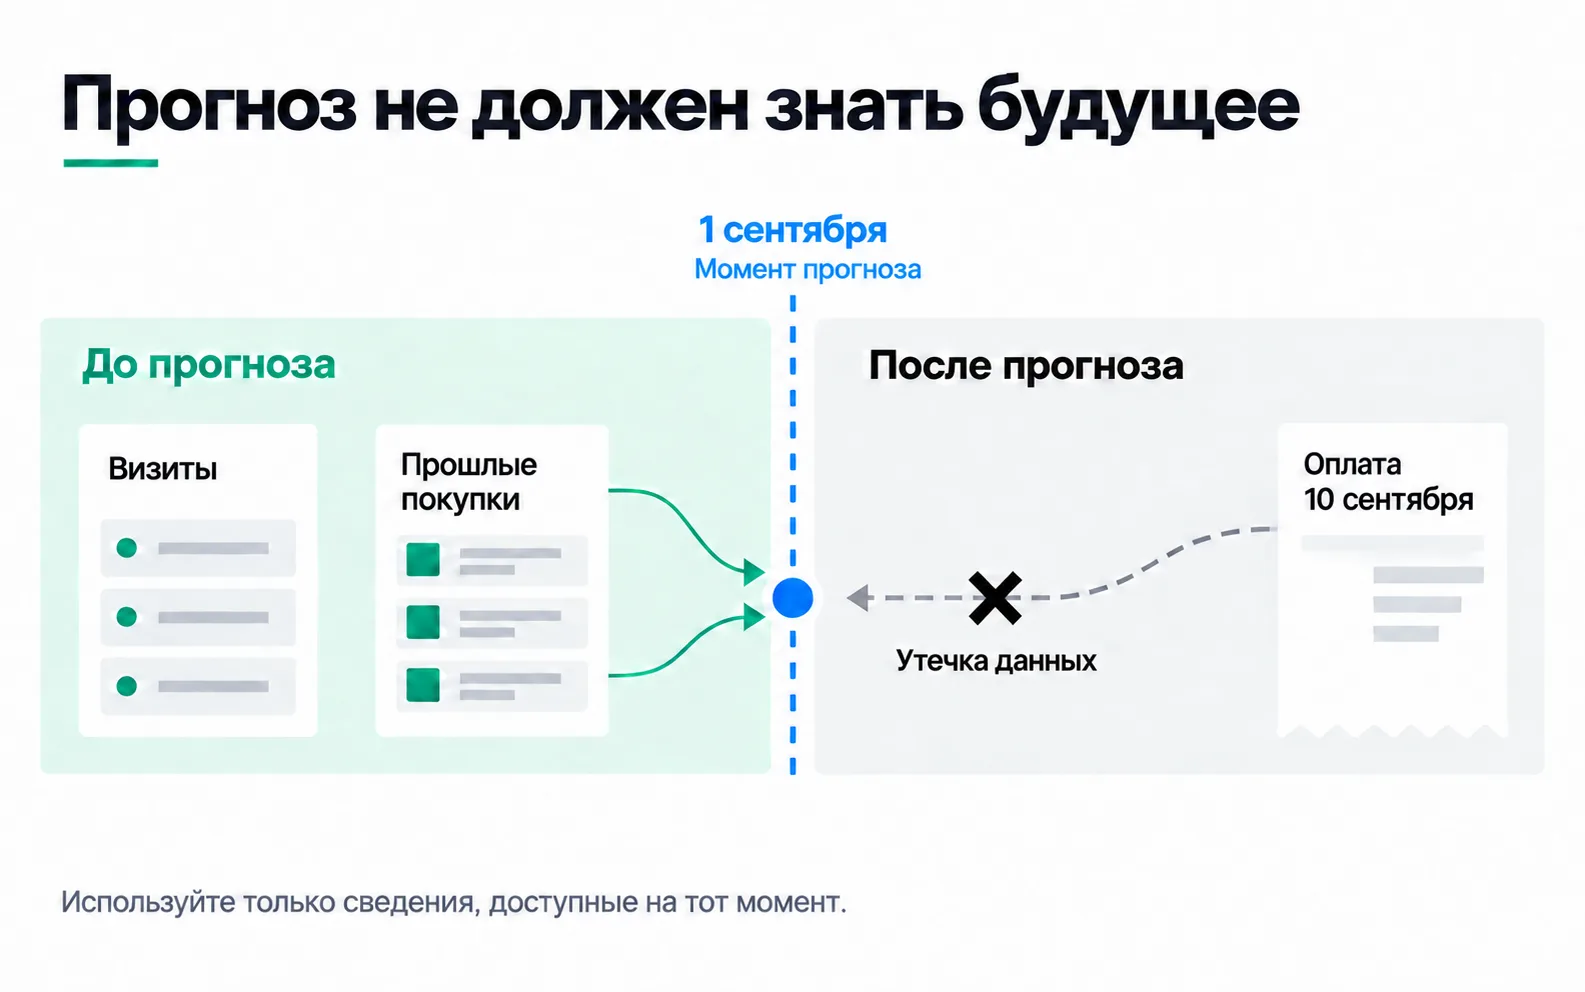
Define the event and decision time
“Find good customers” is not a measurable target. A more precise outcome is payment within 30 days of receiving an enquiry. Then define when the prediction is made and what it changes: call priority, an offer of help or inventory planning. Without an action, a high score may remain just a number in a report.
Each record needs a reference point, information available then and the later outcome. Yesterday's enquiry has not completed its 30-day window. Do not classify it as negative simply because no payment exists today. Quality assessment needs records whose observation period has finished.
Define the target beforehand. Payment, revenue after refunds and contribution after variable costs are different outcomes. A model trained to find enquiries is not yet a profit forecast. First establish a connection to the business outcome and test that connection separately.
The selection threshold also depends on workload. If salespeople can handle 100 enquiries, assess the selected 100 under one working procedure. Comparing with a rule that sends them substantially more records would mix selection quality with effort.
Reconstruct the information available before prediction
Future information can enter through an unremarkable field. Current CRM status, total purchases and the closing reason may include events unavailable at decision time. Putting an old date on today's customer row does not create a historical snapshot.
For each field, check both event time and when it became available in production. An employee may enter yesterday's call later. An earlier prediction could not access that record even though the call had occurred. Availability history helps reproduce the conditions of use.
Google's material on ML monitoring covers outcome leakage and differences between training and serving. The team's practical task is to reconstruct the fields the system can actually obtain before the chosen action.
Evaluate on data held apart from training that resembles future use. With a time-based split, training outcomes must have matured before the boundary, and feature preparation must not use the evaluation portion. Also consider whether future customers will be new or predictions will repeat for known customers. Otherwise the assessment may answer a different question.
Calculate precision and recall for the selected group
The evaluation sample has 1,000 leads, of whom 50 paid. Always predicting “will not buy” correctly classifies 950 records. Accuracy, the share of correct answers, is 950 / 1,000 = 95%. Yet no buyer enters the priority list.
Another model selected 100 leads, 20 of whom bought. We can now see both found buyers and misses:
| Question | Calculation | Result |
|---|---|---|
| What share of those selected bought? | 20 / 100 | Precision = 20% |
| What share of all buyers did we find? | 20 / 50 | Recall = 40% |
| How many selected leads did not buy? | 100 - 20 | 80 |
| How many buyers remained outside the priority list? | 50 - 20 | 30 |
Google's classification metric definitions help read these numbers together. High precision in the selected group can coexist with many missed buyers. Choose a threshold around error costs, available work and the purpose of selection.
A score of 80 is not an 80% probability. That interpretation requires calibration assessment: whether stated probabilities agree with outcome frequency on appropriate data. Without it, a validated score may rank records, but it should not acquire a percentage label.
A simple rule provides a useful reference. For example, the queue could use a feature already available to salespeople. Assess both approaches on comparable data with equal workloads. Model complexity is justified only when its result helps the process and covers the cost of maintaining it.
Price the action separately from selection
Suppose handling one priority lead costs the team 500 ₸ of staff time at an internal planning rate. This is an illustrative value, not a market rate. Work on 100 selected leads costs 100 × 500 = 50,000 ₸. Contribution from an additional purchase after variable fulfilment costs, before contact and model costs, is assumed to be 5,000 ₸.
Covering the assigned value of that work requires 50,000 / 5,000 = 10 additional purchases. The 50,000 ₸ values time, not new payments. Model development and maintenance are excluded for now and must be added for the full decision. The 20 buyers identified by the model cannot automatically count as additional: some would buy without a call.
A purchase propensity forecast describes the chance of an event under given conditions. The effect of a call or discount is the behavioural change caused by the action. Assessing it needs a properly randomised split of a suitable audience or another justified causal comparison. Calculate contribution after contact and offer costs separately.
An action can be unnecessary even with good selection. If customers ready to pay full price receive a discount, contribution may fall without more purchases. Reports therefore need forecast quality alongside the result of a tested action. The first measure cannot replace the second.
Plan for errors and changing data
A prediction needs an owner, a useful lifetime and a clear next action for staff. A low score describes an estimate from a chosen model, not a person's worth. Define what happens to a record outside the priority list and which help the user still receives.
Retain the model version, input information, forecast and action taken. Missing fields, a changed source or delayed updates need a response before incorrect decisions accumulate. A manual queue or an earlier validated rule can provide a fallback.
After launch, assess quality using new matured outcomes and track staff workload. Changes in the product or acquisition channels may alter incoming leads. A strong historical result remains a starting point to compare against current performance.
Exercise: explain 30 buyers out of 100
A separate sample contains 1,000 leads and 60 buyers. The model selected 100 leads, of whom 30 bought. Find precision and recall, then explain what is missing to assess the value of a call. For your project, record the prediction time, target event and a field that might accidentally reveal the future.
Precision is 30 / 100 = 30%; recall is 30 / 60 = 50%. Another 30 buyers remained outside the priority group. These figures describe selection. Attributing purchases to a salesperson needs comparison with behaviour without that action and a cost calculation.
For a project with leakage, the first correction is to restore features available in time and reassess the forecast. For a project with good selection but unknown call value, the next task is to test the action. The implementation decision then rests on both parts of the process.