A team chose the idea with the highest RICE score. Clicks rose after launch, and the report already calls it a win even though payments are still pending. At the next meeting, the new variant turns out to have more refunds.
Write your decision before reading the analysis. The task figures are illustrative. This is a written self-check, producing a calculation and a plan that another person can examine.
Case: two ideas in the queue
The team scores two registration changes. Reach means unique customers affected over a quarter. Impact uses a shared scale, Confidence is a fraction, and Effort includes every participant's work in person-months.
| Idea | Reach | Impact | Confidence | Effort |
|---|---|---|---|---|
| A: simplify the registration step | 1,000 | 1 | 0.8 | 2 |
| B: add a completed example | 500 | 2 | 0.5 | 1 |
Calculate RICE as Reach × Impact × Confidence / Effort. Explain what one row's advantage means. Then change the conditions: B requires part of A to be completed first. How does this affect the choice?
Analysis: priority rests on estimates
A scores 1,000 × 1 × 0.8 / 2 = 400. B scores 500 × 2 × 0.5 / 1 = 500. Under the recorded assumptions, B ranks higher. The difference represents expected benefit relative to effort within the chosen model, rather than a measured effect of an implemented change.
Intercom's RICE method combines reach, impact, confidence and effort. Comparison requires a shared horizon and reach unit, clear grounds for the estimates and the full workload. Confidence of 0.5 weights confidence in those estimates; it is not a measured 50% probability of success.
If B first requires part of A, its effort must include that dependency unless already counted. Compare feasible packages of work. B cannot simultaneously be treated as an independent cheap task while its required development is assumed complete.
An uncertain estimate can be investigated before a major build. For example, establish whether people understand the completed example and whether it helps them pass the difficult step. That check informs an assumption but does not replace measurement of the commercial outcome. This is the purpose of hypothesis prioritisation: make the grounds for a choice visible and open to revision.
Effort is the denominator in RICE: more work lowers the score. Ease in ICE measures simplicity, so increasing it acts in the opposite direction. The team's table needs the chosen formula and scales; otherwise the same word “priority” can hide different calculations.
Case: clicks are declared a win
Before launch, the team chose the share of customers with a paid order as the primary metric, with payment errors as a guardrail. Clicks increased in the first days, but the agreed payment window has not closed. The manager proposes making clicks the primary metric and ending the test.
What can be reported now? What should the plan have contained before launch? How should the team handle an error discovered in the protocol?
Analysis: retain the decision rule
The current evidence concerns an intermediate action. The answer about completed payments is not yet available. Keep the original metric and open observation window in the log; record clicks separately. Replacing the outcome after seeing the data changes the question the experiment was designed to answer.
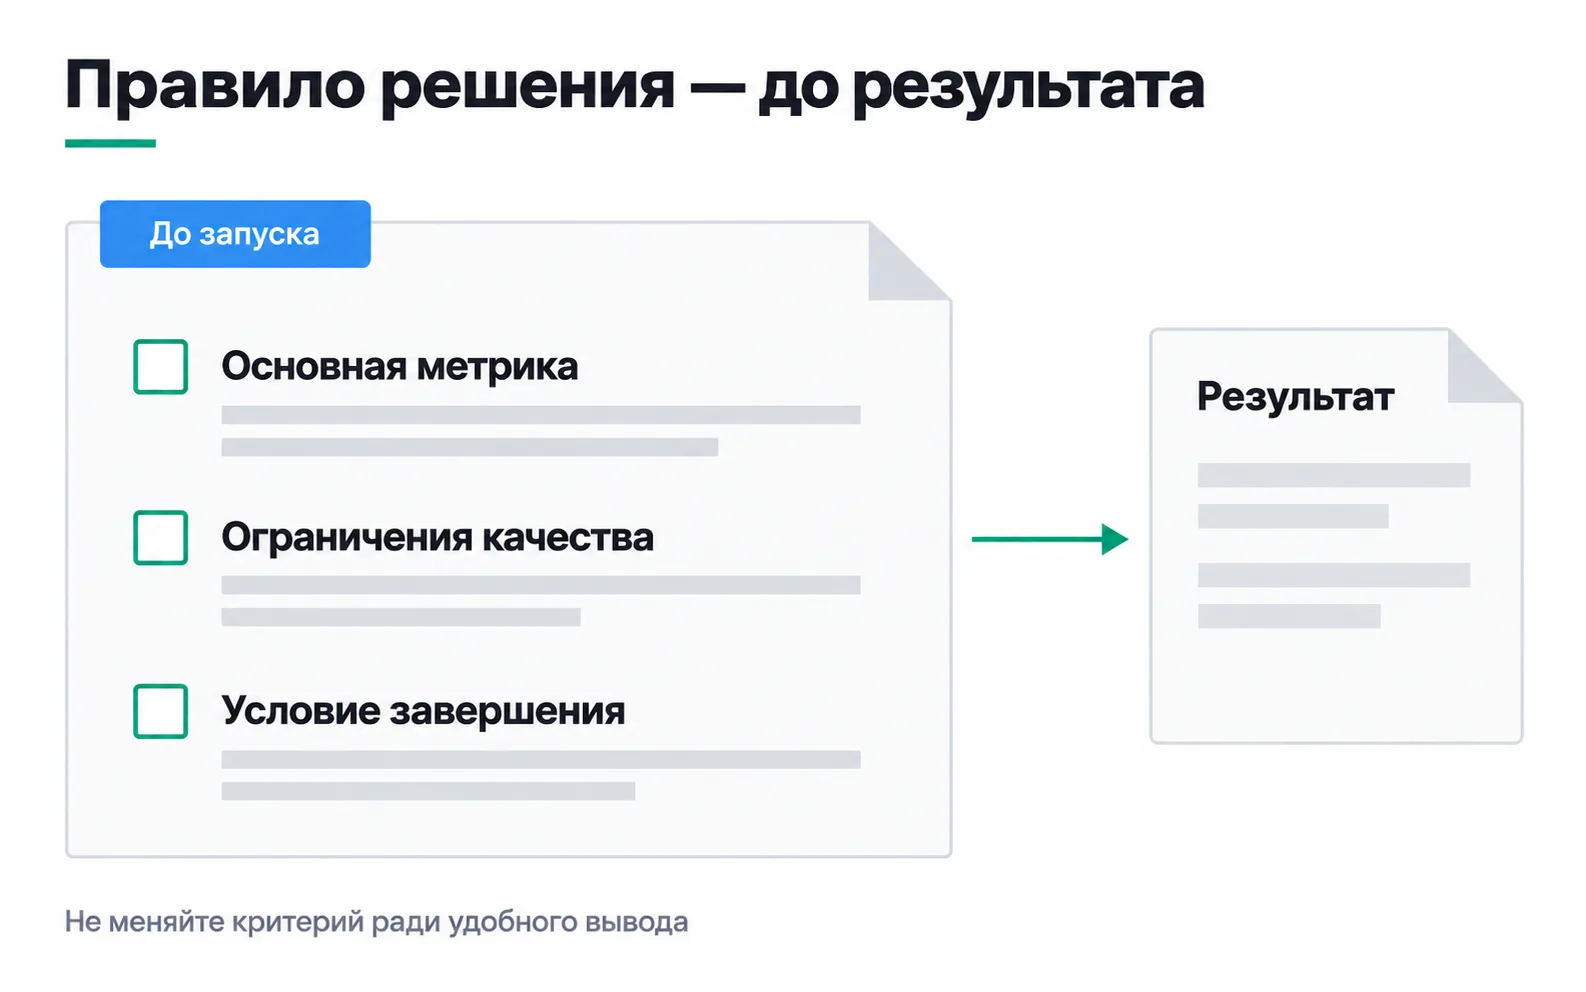
The plan includes the audience, assignment unit, assignment method, primary metric, guardrails, outcome window and completion rule. Sample size depends on the baseline rate and the change that matters for the decision. Set the final reading date and the response to a shortfall before starting.
The coffee reorder reminder already has such a plan. Comparing 25% versus 33% at 5% significance and 80% power requires 473 people per group, 946 in total. About 100 consenting newcomers a month corresponds to an input of 3.33 people a day: 285 recruitment days followed by 60 days of observation, with the final reading on day 345. This is a separate coffee-shop test, not the registration example in the RICE table.
Even IDs receive the reminder and odd IDs remain in the holdout. Assignment precedes the flow's actions and is suitable only if parity is independent of channel, date and branch; otherwise a different random assignment method is needed before launch. The comparison retains all assigned participants, including those who did not read the message.
Interim readings are scheduled for approximately months five and eight: closed windows for the first three and six recruitment months, around 150 and 300 people per group. They do not change the decision date based on the observed effect. If a group has fewer than 473 participants with closed windows on day 345, the report records the shortfall and uncertainty. Extending the test until a convenient result appears is outside the plan.
A measurement fault needs its own record: what failed, which data were affected and which new check is required. Give the corrected protocol a version. Renaming a column cannot turn old data into confirmation of a new hypothesis. Stopping for a predefined customer risk remains possible, but record it as a protective decision without declaring a winner.
Case: more paid orders, less contribution
In another shop experiment, 1,000 buyers were randomly assigned to each of A and B. Each contributes at most one order. Recruitment periods and observation windows match; payments and refunds have completed the agreed horizon. Before launch, the team decided not to expand a variant if refunds exceeded 8% of paid orders.
| Measure | A | B |
|---|---|---|
| Paid orders before refunds | 100 | 110 |
| Fully refunded orders | 5 | 15 |
| Order price | 10,000 ₸ | 10,000 ₸ |
Each retained order contributes 4,000 ₸ after variable product and fulfilment costs. A full refund returns the money to the buyer and restores the goods and their cost; a separate 1,000 ₸ covers all non-recoverable costs of that order, including fulfilment and refund processing. The case contains no other non-recoverable costs for a refunded order. This is an assumption of the task. Advertising, development and fixed costs are excluded for now.
Calculate the payment rate, refund rate and each group's contribution after refund costs. Are more payments enough to roll B out to everyone?
Analysis: the guardrail belongs in the result
Payment rates are 100 / 1,000 = 10% for A and 110 / 1,000 = 11% for B. The observed difference is 1 percentage point. Its uncertainty still needs assessment using the planned method; percentages alone are insufficient to declare a winner.
Refund rates are 5 / 100 = 5% and 15 / 110, approximately 13.6%. B exceeds the predefined 8% limit, so that rule postpones expansion. If recording is wrong, repair the data first. If the refunds are real, investigate the product, promise and purchase journey before deciding how to revise the variant.
Each group retains 95 orders after refunds. A's contribution is 95 × 4,000 - 5 × 1,000 = 375,000 ₸. B's is 95 × 4,000 - 15 × 1,000 = 365,000 ₸. Despite its higher payment rate, B contributes 10,000 ₸ less within the task's boundaries. This is not the project's complete profit: excluded costs must be added separately.
The log should retain both metrics, the financial calculation, the breached guardrail and the decision not to expand the current variant. “Payment win” would hide evidence that changes the decision.
Exercise: write your own experiment protocol
Choose one project hypothesis. Record the change, expected mechanism and metric, followed by the audience, assignment, sample, window, guardrails and final-reading rule. Add costs and a formula for the commercial outcome. Describe separately an outcome that would leave insufficient evidence.
The completed protocol lets a colleague see what will change and which observation will support a decision. If the hypothesis promises purchases but the plan measures only clicks, the connection needs work. If duration depends on when the desired difference appears, the completion rule is still missing. A HADI cycle ends with a conclusion from the evidence, including a conclusion about missing knowledge and the next check.